AI Tech36氪
A Gamble Reshaped by the 'Lobster': Has Meta's Second Comeback Failed?
AI Summary
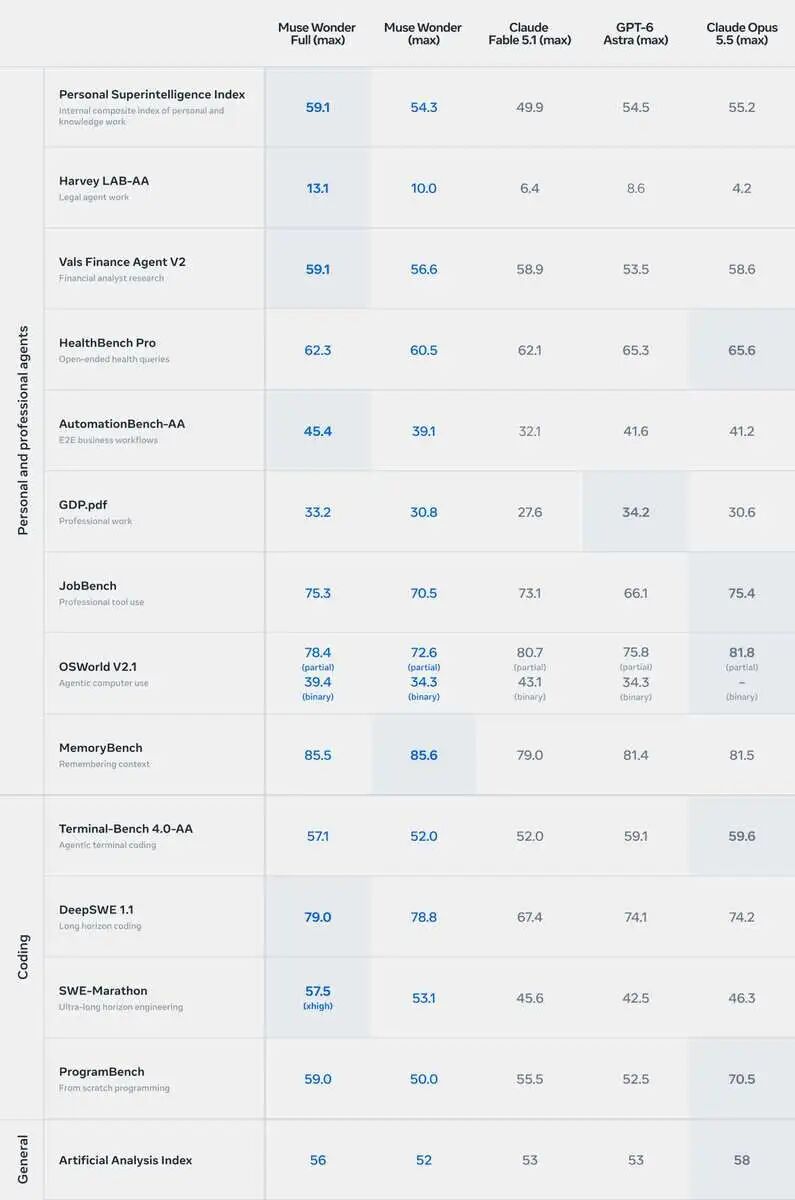
Meta has launched Muse Wonder, a new flagship model series built on its personal AI agent app Muse, challenging OpenAI and Anthropic again. While it ranks near the top on benchmarks, developers have criticized its real-world performance, and its high inference costs and pricing are drawing scrutiny.
AI Insights
Meta's Muse Wonder shows strong benchmark results, especially in long-horizon coding and memory tasks, but developer reception and high inference costs (about 183% higher per task than its predecessor) suggest a gap between leaderboard performance and real-world value. The strategy of gating the larger model behind paid tiers while aiming to compress its capabilities into lighter models signals that competitive pricing and efficiency, not just raw scores, will determine whether Meta can regain ground against OpenAI and Anthropic.
Analysis written by AI from the original article. Check it against the source.
Translated text
Related News
AI Tech36氪
Anthropic Shocking Study: AI Could Self-Replicate Through TV Boxes
Anthropic's Frontier Red Team published research examining whether AI could replicate, run, and spread across devices autonomously, like a computer virus. The team ran a 26B-parameter model across 15 low-cost Android TV boxes and found that small models can increasingly adapt to unfamiliar hardware. The experiments were conducted in isolated environments, not real-world networks.
AI Tech36氪
Google Awakens to Physics: Gemini 4 Argon Hands-On Tests Pour In
Google's Gemini 4 Argon has launched and reportedly competes closely with GPT-6 Astra and Claude Opus 5.5 on benchmarks, at about one-fifth the price and several times faster. Hands-on tests showed strengths in 3D generation, physics-intuitive visualization, and scientific reasoning, though its Chinese-language narration sounded awkward.
AI Tech虎嗅
Hands-On Test of Gemini 4 Argon: Google's Stumbling Last-Ditch Effort
Google has made Gemini 4 Argon generally available after first announcing it on October 1 for a security program. Following a year of talent departures and delayed model launches, the model is widely seen as a last-ditch effort for Google. Hands-on testing suggests it will struggle to challenge Claude Opus 5.5 or GPT-6 Astra.